


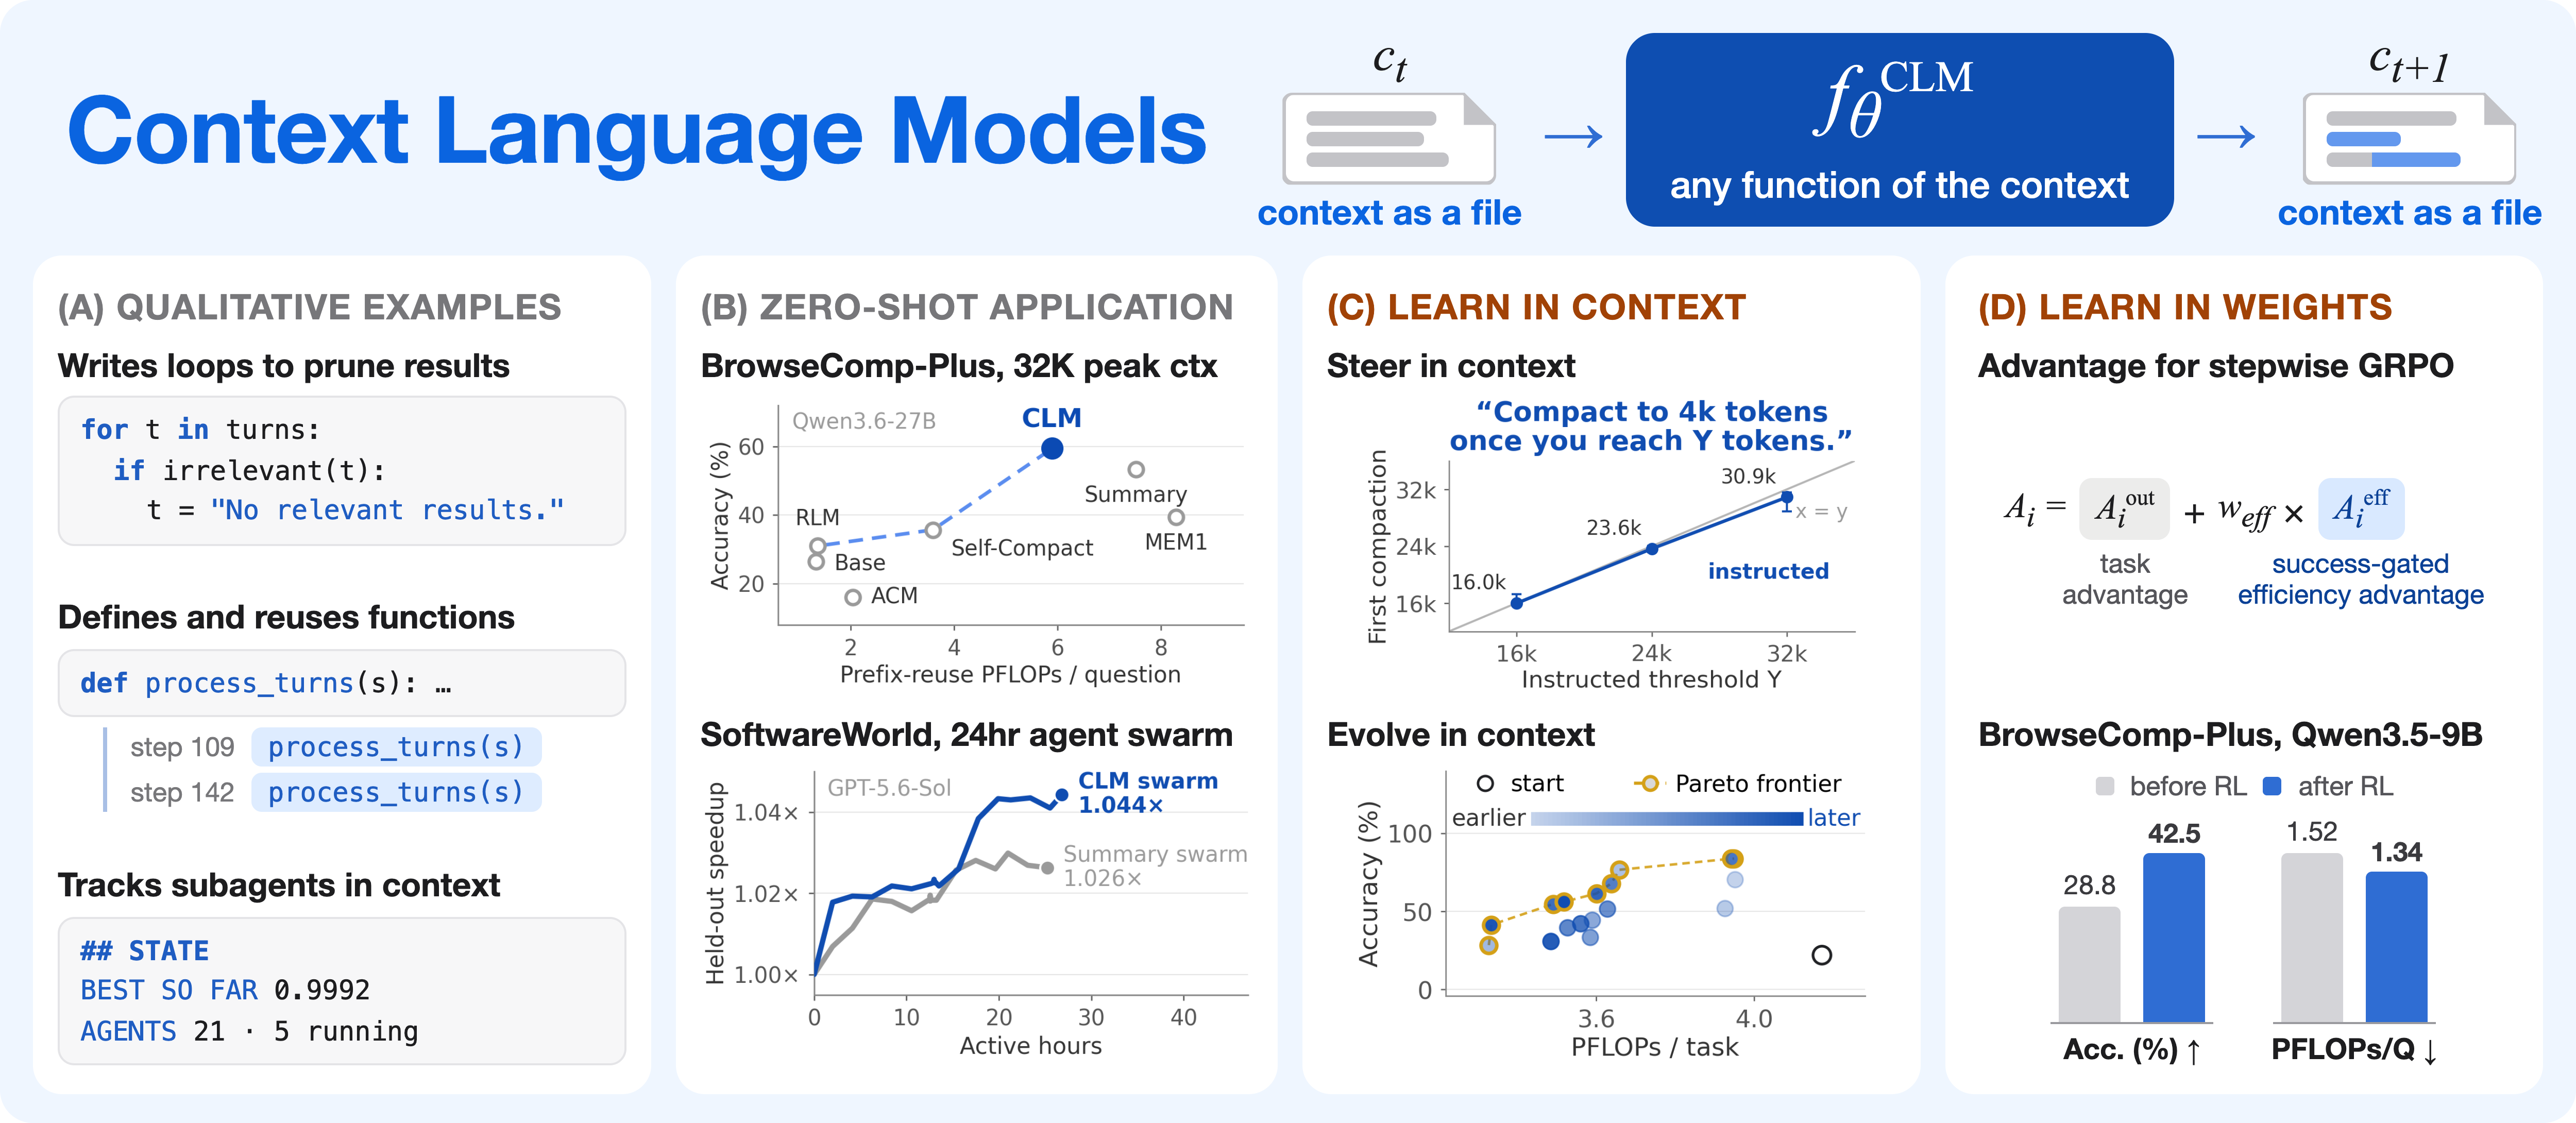
Figure 1, Shao et al., Context Language Models. CC BY 4.0.
In one minute
The details
Agents rewrite their own context - 9/10
Takeaway: Letting agents edit their context can beat summarization, but production tests still need cache-aware costs and protection against persistent prompt injection.
What changed: A new Context Language Models paper exposes live context as an editable file, with code and reported accuracy-efficiency gains on research and coding tasks.
Sources: arXiv paper: Context Language Models, GitHub facebookresearch/context-language-models
Kumo brings pretrained models to tables - 9/10
Takeaway: A pretrained table model can remove task-specific training, but labeled context and held-out validation still do the hard work.
What changed: NVIDIA released 28M-215M Kumo Tabular weights and inference code for classification and regression; its training recipe is still forthcoming.
Sources: Hugging Face blog/nvidia: NVIDIA on Hugging Face: Kumo Tabular, Hugging Face nvidia/Kumo-Tabular model card, GitHub NVIDIA/structured-data-models
Dots makes background agents a product - 8/10
Takeaway: Always-on agents make scope and review rules part of the product; background awareness is different from permission to act.
What changed: OpenAI introduced GPT-6 Astra-powered Dots with cloud computers and connected apps, rolling out to eligible Pro and Business Premium users and an admin-enabled Enterprise beta.
Sources: OpenAI blog: introducing Dots
GPT-6.1 Sol lowers token prices - 9/10
Takeaway: A cheaper token is useful only when the task still passes; compare complete runs, reasoning effort, and cache hit rates.
What changed: OpenAI released GPT-6.1 Sol at $2 input, $0.10 cached input, and $10 output per million tokens, with vendor-reported near-Astra results on several benchmarks.
Sources: OpenAI blog: GPT-6.1 Sol
Also worth knowing
DeepGEMM arrives on Ascend (8/10): DeepSeek released MIT-licensed Ascend 950 kernels; near-peak GEMM numbers are not end-to-end serving benchmarks.
A new GLM-5.3 safeguard study (8/10): Anthropic reports narrow GLM-5.3 cyber tests and safeguard failures, reinforcing the need for access controls outside model refusals.
Ollama adds a local decision endpoint (7/10): Ollama 0.35 adds /v1/systemone for local decision models; returned confidence concentrates predictions but is not calibrated correctness.
More links
X/Twitter @cursor_ai: Cursor adds /visualize. (6/10 / context). A small Agents Window addition for generating charts and diagrams.
Quick feedback
Send what was useful and what should change in the next edition.